Speech Synthesis Voice Lists: A Safe Troubleshooting Guide
Handle empty voice lists, locale matching, speech queues, and errors without treating voices as an identity signal.
BotBrowser Team
Prefer the maintained product doc?
This article has a matching page in the docs center. Use the docs for the canonical setup flow, current flags, and long-term reference.
BotBrowser's profile mode controls exposed voice metadata, but it does not guarantee that the host can produce audible speech.
If a browser voice picker is empty, do not immediately treat the API as unsupported or keep polling forever. Read getVoices(), subscribe to voiceschanged for a bounded refresh, then preserve readable text and offer a retry or application-locale fallback if no suitable voice appears. Start speech from an intentional user action, resolve the selected voice against the current list, and handle queue completion, cancellation, and errors as ordinary application states. The available voice metadata can vary, so it is not a stable device identity or a cross-operating-system catalogue.
TL;DR
getVoices()can return an empty array at a particular moment. Treat that as a loading or availability state and refresh aftervoiceschanged; do not assume a fixed event count or timing.name,lang,localService,default, andvoiceURIanswer different questions. Match a voice to the reader's task and locale, not to a presumed operating-system sequence.speak()adds an utterance to the speech queue. A list refresh is not a reason to enqueue the same utterance again; refresh the choice, then let the reader decide whether to start or replay.- Invoke playback from a visible user action, but do not promise that every browser has the same permission prompt or activation policy. Keep the original text and a retryable error state available.
- A voice list can reveal environment context without identifying a person. Collect the minimum diagnostic needed and do not transmit a complete inventory by default.
Contents
- What the API exposes
- A field-by-field selection rule
- Fault tree for a voice picker
- Refresh and speech queue states
- Locale fallback and user activation
- Cancellation, errors, and privacy limits
- What this adds to the configuration guide
- Practical conclusion
What the API exposes
The Web Speech API separates voice discovery from spoken output. window.speechSynthesis is the controller: it exposes the current voice list, a queue, and methods such as speak(), cancel(), pause(), and resume(). A SpeechSynthesisUtterance carries the text and optional settings for one request. The application can read voice metadata before asking the controller to speak; enumerating voices does not itself require playing audio. Reading the list with getVoices() has no separate user-permission request in the API; policies for starting audio playback are a separate matter.
The list is contextual rather than universal. A browser may integrate with operating-system speech services, a browser-managed service, or both. Installed language resources and browser choices can influence what is exposed. Even on one host, two browser products or releases need not return an identical collection. A machine can also change after a language pack or service is installed. Therefore, do not publish a table that claims every Windows, macOS, Linux, or mobile installation has a fixed count, brand, ordering, or set of names.
The first call is not a reliable readiness test. MDN documents that getVoices() returns the voices currently available to the speech synthesis service and documents the voiceschanged event for a change to that list. Some application environments observe an initially empty list followed by a change event; others may have entries available at the first read. The API does not give an application a universal delay after which a list must be complete. A page should support both the immediate-list and refresh paths instead of turning a particular timing into a compatibility guarantee.
This surface matters to privacy because the names, language coverage, locality flags, and change behavior may add context to other browser signals. For the wider concept of combining unrelated browser attributes, see browser fingerprinting explained. The existence of a potentially distinctive set is not proof that a site uses it, that it identifies a person, or that any one property maps to a specific operating system. A user-facing voice picker needs only enough information to make a useful choice; routine analytics rarely need the complete list.
A field-by-field selection rule
Voice objects expose fields with separate purposes. A useful picker does not treat them as interchangeable identifiers.
| Field | Useful application question | Selection rule | What not to infer |
|---|---|---|---|
lang | Which language or locale is represented? | Compare language tags with the app's requested locale, preferring an exact match before a deliberate language-level fallback. | A matching tag does not guarantee that the text is translated or pronounced as expected. |
name | What label can help a person distinguish options? | Show a concise, escaped display label when a choice is needed; keep it local unless support requires it. | A brand-like name is not proof of an OS, device, or person. |
localService | Does the API describe the service as local? | Use it only when the app has a user-facing reason to explain local versus remote service behavior. | true is not a promise about network privacy or successful playback. |
default | Which voice does the implementation mark as its default? | Use as a tie-breaker among otherwise suitable voices when the reader has not chosen one. | The default is not necessarily the app's preferred language or the best match for the current text. |
voiceURI | Is there an implementation-provided URI for a voice? | Treat it as an opaque value; avoid persisting it or using it as a cross-session key. | It is not guaranteed to be globally stable, portable, or meaningful outside that implementation. |
The table is a decision aid, not a list of platform signatures. On one installation a name may be human-readable while another identifier is opaque; an application should not parse the name to infer a vendor. A value of localService describes the voice object according to the implementation, not the complete route taken by every speech request. Likewise, default is a preference supplied by the implementation, not a language negotiation algorithm for the page.
Start with the app's actual requirement. If it needs to read Spanish text, select from voices whose lang matches the requested Spanish locale as closely as the current list permits. If there are several matches, use an explicit user choice or a predictable tie-breaker such as default. If the page only needs to offer a play button and has no voice menu, it may not need to display or persist names at all. For a related example of keeping declared platform properties in context, see navigator properties and platform context; neither surface should be treated as a personal identity key.
Do not assume a stable sequence such as “voice zero is the system default” or “the first English entry is the same on all computers.” Array order is not a portable selection contract. Refresh can also produce a new array, so an application should retain a user-facing preference such as the requested locale or a locally selected option, then resolve that preference against the latest objects. If the former choice is missing, tell the reader and offer the remaining matches rather than silently selecting an unrelated voice.
Fault tree for a voice picker
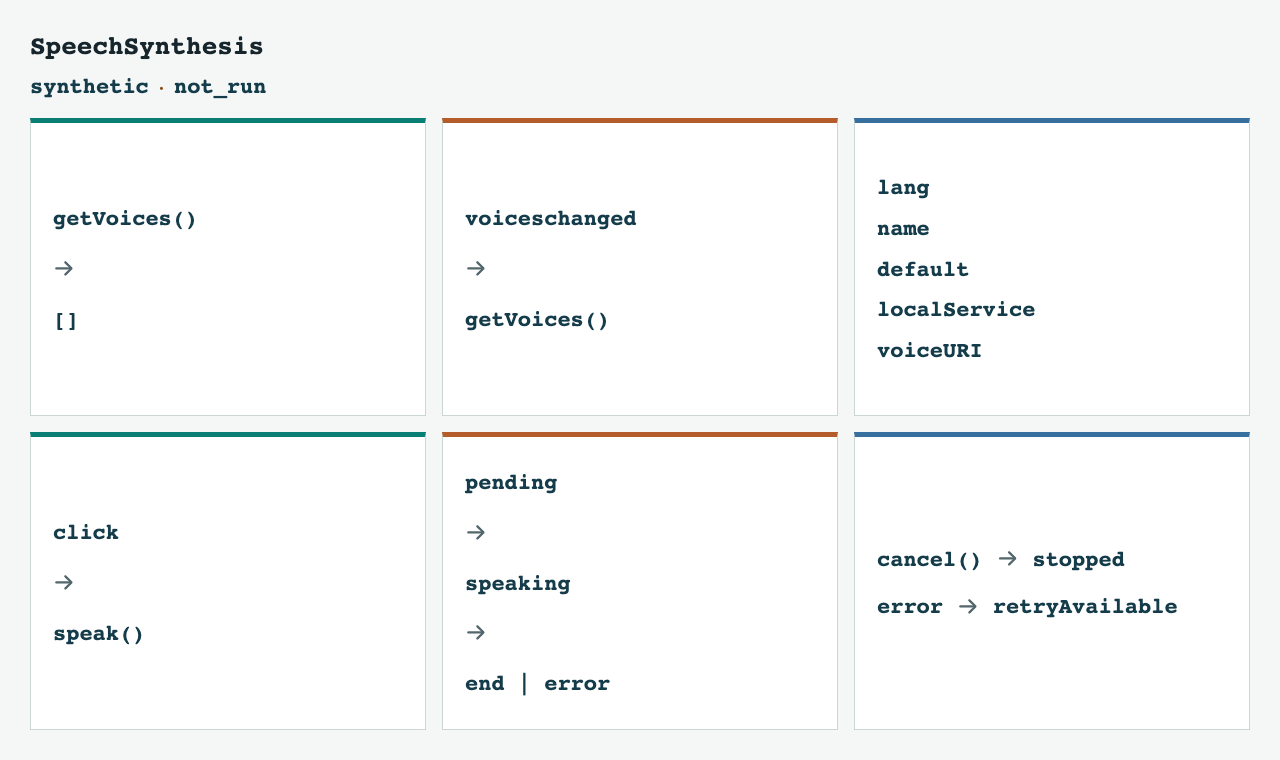
The following decision path keeps an application useful without converting a transient API state into a claim about the browser or device:
- Is
speechSynthesispresent? If not, leave the written content available and show that read-aloud is unavailable in this context. Do not hide or replace the text. - Does
getVoices()return entries now? If yes, render choices from the current list. If no, register onevoiceschangedlistener, read again when it fires, and stop waiting after an application-defined timeout. Do not create a new listener on every render. - Did a refresh provide a suitable
lang? If yes, retain the user's selected choice when it still matches. If it disappeared, clear the stale selection and explain the available alternatives. If no voice matches, use the app's explicit locale fallback or ask the person to choose; do not infer a language from a voice name. - Did the person activate playback? If yes, construct a fresh utterance using the current choice and call
speak(). If no, wait. This keeps the feature under reader control and avoids relying on an autoplay assumption. - What happened to the utterance? On
end, expose the idle or completed state. Onerror, show a concise retryable message and preserve the text. On an explicit stop, cancel the queue and clear the active UI state. - Did the list change during playback? Update the picker, but do not duplicate the active utterance. Before a later replay, resolve the preferred choice against the latest list.
An empty array after a bounded wait has several possible explanations: speech synthesis might not be usable in the current context, a service may not have supplied entries, the application may be looking for the wrong locale, or initialization may not have completed in the way the application expected. Those possibilities call for different user actions. A generic “fingerprint mismatch” message is neither useful nor justified. A narrow message such as “No voice for French is currently available” is actionable and does not reveal the full inventory.
The diagram above condenses these branches into six application states. It is an illustrative decision aid rendered from a local HTML fixture, not a captured browser measurement. The key result is that the interface always retains a text path, whether the list arrives immediately, changes later, or remains empty.
Deciding when a wait is over
| Evidence the list is still loading | What it can and cannot prove |
|---|---|
getVoices() returned an empty array on first paint | Not final by itself; the list is filled asynchronously |
voiceschanged has not fired yet | Not final; the event may still arrive |
A read after voiceschanged is non-empty | The list is ready to use |
| The timer expires with an empty list | No voices appeared within your wait; this is not proof that none exist |
A voiceschanged event that returns the same list proves the event fired, not that the list is complete. Only a non-empty read is a positive result, so report the empty timeout as "still empty after 2 s" and keep the retry and the fallback text.
The difference between "not yet" and "none" decides whether the interface shows a spinner, a retry, or a locale message, and the two look identical in a single getVoices() call. Three questions separate them without guessing.
Read once at load and keep that result. An empty array on first paint is normal on some platforms, because the list is populated asynchronously. Record it as the first sample rather than as a verdict, and render the picker in a loading state.
Bind exactly one voiceschanged listener for the life of the component, and read again inside it. A non-empty read means the list is ready. An unchanged read means the event fired while the list stayed empty; that is not a promise from the platform, so keep it as "still empty" rather than "none available".
Cap the wait with an application timeout, and treat the timeout as a status, not a failure. When it expires with an empty list, remove the listener, clear the timer, stop the spinner, and show the locale message with the text still readable plus a retry. A page that waits forever, or keeps a stale listener, has converted a platform detail into an unusable control.
const readOnce = () => speechSynthesis.getVoices();
const key = list => list.map(v => `${v.voiceURI}|${v.lang}|${v.name}`).join('\n');
let first = readOnce();
let settled = false;

const settle = new Promise(resolve => {
  const finish = outcome => {
    if (settled) return;
    settled = true;
    clearTimeout(timer);
    speechSynthesis.removeEventListener('voiceschanged', onChange);
    resolve(outcome);
  };
  const timer = setTimeout(() => finish('still-empty'), 2000);
  const onChange = () => {
    const next = readOnce();
    // A change event with the same list proves the event fired, not that the list is final.
    if (next.length) finish('ready');
    else if (key(next) !== key(first)) finish('still-empty');
  };
  speechSynthesis.addEventListener('voiceschanged', onChange);
  if (first.length) finish('ready');
  // If no event arrives, the 2 s timer reports 'still-empty': neither ready nor proven absent.
});
The three outcomes map to three different screens, and none of them is "speech is unsupported". A non-empty first read goes straight to the picker. A late non-empty read lands on the picker after the loading state. A timeout with an empty read shows the locale message and keeps the text. The same code produces all three, so the difference is what the platform reported, not what the device is.
Refresh and speech queue states
The voiceschanged event indicates that the list returned by getVoices() has changed. It is not an instruction to speak again, and an application should not assume it fires exactly once. A clean refresh routine replaces the displayed list from the latest call, removes a one-shot listener after use, and keeps the user's locale preference separate from a particular SpeechSynthesisVoice object. If the app supports a manual retry, it can call the same routine rather than adding another event handler.
SpeechSynthesis.speak(utterance) adds the utterance to the controller's queue. Repeated clicks or repeated refresh callbacks can therefore create duplicate speech unless the interface defines its policy. A product can disable its play button while an utterance is queued or speaking, provide a separate “stop” action, or deliberately replace the current request. The important point is to make that transition explicit. A change to the available choices alone should not create a new queue entry.
The following code is illustrative and has not been run. It shows one bounded refresh, locale matching, and an explicit user-triggered playback path. It is not a promise that every browser exposes the same voices or accepts playback in the same circumstances.
This example demonstrates automatic locale matching only; it does not implement saving or restoring an explicit user voice selection.
const synth = window.speechSynthesis;
const requestedLocale = 'en-GB'; // Set from the application's own locale.
let currentVoices = [];
let activeUtterance = null;
let refreshTimer = null;

function refreshVoices() {
  currentVoices = synth.getVoices();
  const exact = currentVoices.filter(voice => voice.lang.toLowerCase() === requestedLocale.toLowerCase());
  const language = requestedLocale.split('-')[0];
  const broader = currentVoices.filter(voice => voice.lang.toLowerCase().split('-')[0] === language.toLowerCase());
  return exact.length ? exact : broader;
}

function waitForVoices(onReady, timeoutMs = 1500) {
  const immediate = refreshVoices();
  if (immediate.length) {
    onReady(immediate);
    return;
  }

  const onChange = () => {
    const matches = refreshVoices();
    if (matches.length) {
      clearTimeout(refreshTimer);
      synth.removeEventListener('voiceschanged', onChange);
      onReady(matches);
    }
  };

  synth.addEventListener('voiceschanged', onChange);
  refreshTimer = setTimeout(() => {
    synth.removeEventListener('voiceschanged', onChange);
    refreshTimer = null;
    onReady(refreshVoices());
  }, timeoutMs);
}

function playFromUserAction(text) {
  const available = refreshVoices();
  const voice = available.find(item => item.default) ?? available[0];
  if (!voice) {
    showReadableRetryState();
    return;
  }

  const utterance = new SpeechSynthesisUtterance(text);
  utterance.lang = voice.lang;
  utterance.voice = voice;

  activeUtterance = utterance;
  utterance.onend = () => {
    activeUtterance = null;
  };
  utterance.onerror = () => {
    activeUtterance = null;
    showReadableRetryState();
  };
  synth.speak(utterance);
}

function stopSpeech() {
  synth.cancel();
  activeUtterance = null;
}
In a production component, onReady should update a picker or a visible availability state, not serialize every voice into analytics. The example also assumes that showReadableRetryState() is supplied by the application. A real interface should ensure that event handlers cannot update a component after it has been removed, clear any outstanding timer during cleanup, and decide what a second playback action does while speech is active. Those are ordinary lifecycle decisions; they are not properties that can be inferred from voice metadata.
Locale fallback and user activation
Voice selection should follow the application's language policy, not an operating-system guess. Derive the requested locale from the content or an explicit app setting. Try an exact locale such as en-GB first. If the app's product requirements allow it, use a clearly documented language-level match such as en-US. If only an unrelated language is available, do not silently play it as though it were equivalent. Keep the text visible and let the reader choose another option or continue without speech.
A lang value belongs to the voice description and an utterance can also carry a language tag. Neither one translates the text. A voice may be listed for a locale but still pronounce a name, abbreviation, or mixed-language sentence poorly. The product should use translated text where needed and make language controls understandable. The WebRTC codec article is another example of a capability surface where advertised availability should not be confused with a complete end-user outcome.
Speech output should begin after an intentional action such as pressing a “Read aloud” button. This is a user-control and compatibility choice, not a claim that the Web Speech specification defines one universal permission dialog. Browser policies and embedding contexts can affect whether audio starts as expected. The interface should explain how to retry if the request does not start; it should not ask the person to grant a nonexistent API permission or claim that a click guarantees audible output.
When the person changes the app locale, update the requested locale and re-evaluate choices from the current voice list. If a voice refresh occurs while a menu is open, preserve the preference only when it still maps to an available choice. The app can label the fallback clearly, for example “English (United States), used because English (United Kingdom) is unavailable.” A transparent fallback is easier to correct than an automatic switch hidden behind a generic play button.
User choice and accessibility settings should remain independent of analytics. It may be necessary to store a selected option locally for the next page visit, but that does not justify sending the entire voice array to a server. If a service sends text to a remote speech provider, explain that separate data flow and its controls; localService alone should not be presented as a complete network-routing audit.
Cancellation, errors, and privacy limits
The controller's queue needs a visible state model. At minimum, distinguish unavailable, loading, ready, queued or speaking, completed, stopped, and failed. A stop button should call cancel() and return the UI to a predictable idle state; cancellation is an explicit stop, not a retry request. The diagram's retryAvailable label means an application may offer another attempt after explaining an error, and playback must wait for a new reader action. Since cancellation removes pending utterances as well as interrupting current output, a shared page should consider whether one component could cancel speech started by another component. Coordinate ownership instead of letting every widget manipulate a global queue independently.
Attach completion and error handlers to each utterance. Completion can return the play control to its ready state. An error should produce an understandable message, preserve the source text, and offer a meaningful retry or alternative. Do not loop speak() automatically after an error: repeated requests can create a queue or leave the user unsure whether the application heard the stop action. When an utterance is replaced, ignore late callbacks from an older request by comparing it with the currently active request.
The Web Speech API exposes events, but the application should avoid promising a single cause for every failure. A failure could relate to a missing voice, service availability, the text, the browser context, or another platform-specific condition. Report what the application knows, such as “Speech did not start” or “No matching voice is available,” and keep technical details for an opt-in support diagnostic. Do not infer the person's identity, installed software, or location from an error or from a voice's name.
For ordinary support, a compact record can include browser product and version, the app locale, whether any matching voice was available, and the user-visible error category. Avoid recording the full ordered list, every voiceURI, exact timestamps for every list refresh, or content spoken aloud unless a defined support purpose requires it and the person has agreed. Retain such data only for the stated case. The privacy boundary is data minimization, not an attempt to hide a normal application state.
This article does not explain how to identify a person. It describes the metadata as a potentially contextual browser surface and focuses on reliable application behavior. A browser's list does not by itself prove a unique identity, and a local illustrative fixture cannot establish the behavior of every operating system, browser release, language service, or assistive technology.
What this adds to the configuration guide
The Speech Synthesis Protection guide describes BotBrowser's profile and real-system voice modes, their configuration flags, and broad profile-alignment troubleshooting. By default, --bot-speech-voices=profile uses voice metadata from the profile; --bot-speech-voices=real uses system voices without that metadata protection. Neither mode guarantees audible playback. It does not provide a reader-facing application fault tree for an empty initial list, a voiceschanged refresh, a stale selection, or an utterance queue. This article adds a field-by-field selection rule, an unexecuted application example, and explicit UI states for locale fallback, user-initiated playback, cancellation, and errors. Those steps complement the configuration guide; they do not claim to reproduce its profile behavior or add a new product guarantee.
When diagnosing a configuration issue, separate two questions: what voice metadata the browser API returns, and whether the host can produce audible output for the intended user. A profile or configuration guide can address the declared browser surface, while playback depends on the actual application and host context. A successful enumeration check is not an audio test. Conversely, a failed playback request does not prove that a voice list is wrong.
FAQ
Does an empty first call mean speech synthesis is unsupported?
No. It means that the current call returned no voices. The list may be populated later, the environment may provide none, or the API may not be usable in that context. Listen for voiceschanged with a bounded wait, offer a retry, and keep the text available. Do not wait indefinitely or declare a device type from an empty result.
Is voiceURI a stable identifier for saving a preference?
Treat it as opaque implementation metadata, not as a portable account key. Prefer storing the user's language preference and, if needed, a local display choice that can be matched against the current list. If a saved voice is no longer available, ask for a new choice rather than silently selecting a different language.
Does localService: true prove that no network service is involved?
It describes the voice object as local according to the implementation. It does not audit every service path or prove that the entire application keeps text on-device. Explain the actual application data flow separately and avoid turning this Boolean into a broad privacy guarantee.
Should every voiceschanged event trigger speech again?
No. The event is a signal to refresh the available choices. It does not express user intent to play audio. Update the picker, keep or clear the preference based on the current list, and require a separate playback action.
Sources
- W3C Web Speech API: specification for synthesis, voice objects, utterances, queue methods, and events.
- MDN: SpeechSynthesis: browser-facing controller and method reference.
- MDN: SpeechSynthesis.getVoices(): current voice-list method.
- MDN: SpeechSynthesisVoice: voice object properties.
- MDN: voiceschanged event: list-change event.
- MDN: SpeechSynthesis.speak() and cancel(): queue behavior and cancellation.
- MDN: SpeechSynthesisUtterance error event: utterance error event.
- BotBrowser Speech Synthesis Protection: product configuration and profile-mode boundary.
Practical conclusion
An empty or changing voice list is an application state to manage, not a basis for identifying a person or assuming a fixed platform sequence. Refresh with voiceschanged, choose from the current metadata using the app's locale policy, start speech on an explicit reader action, and make completion, cancellation, and errors visible. Keep readable text and collect only the diagnostic fields that support a stated task. The next safe action for a product team is to test both immediate and delayed lists plus a failed utterance in its own supported browser contexts, without claiming that this illustrative code or diagram has already been run.
This article is part of the guide: What Is a Browser Fingerprint?
Related Articles
Speech Synthesis Voices and Accessible Browser Playback
FingerprintWebRTC Codec Fingerprinting: Media Capabilities Leak
FingerprintWebGPU Adapter Information and User Privacy
FingerprintText Measurement Fingerprinting: Sub-Pixel Tracking
FingerprintFrame Rate Fingerprinting: Refresh Rate and Video Timing
FingerprintWhat Is Font Fingerprinting? Cross-Platform Text Consistency
Take BotBrowser from research to production
The guides cover the model first, then move into cross-platform validation, isolated contexts, and scale-ready browser deployment.